A March 2024 follow-up on relighting, game-engine integration, and the gap between neural rendering demos and production use
Topics
Originally published on March 8, 2024. The assessments and expectations below reflect the state of the field and my thinking at that time.
While working at NCSOFT's Vision AI Lab, I wrote a blog post bringing together several results from a project we carried out the previous year.
That article identified two main challenges in using NeRF and 3D Gaussian Splatting in applications such as games:
- Relighting
- Bringing NeRF and 3D Gaussian Splatting results into game engines
I described the approaches available for each challenge at the time. Some time has passed since I wrote it, so I would like to add a few thoughts and observations about developments in the field.
1. NeRF and Relighting
Since the early days of NeRF, researchers have tried to address relighting by learning a BRDF or radiosity alongside the NeRF representation.
$$ L_o (x, w_o) = \int_{\Omega} L_i (x, w_i) f_{\text{BRDF}} (x, w_i, w_o) (w_i \cdot n) dw_i $$
Here, $w_o$ is the outgoing direction, $w_i$ is the incoming direction, and $n$ is the surface normal.
However, estimating BRDF parameters by evaluating the rendering equation over all possible incoming and outgoing reflections while simultaneously training NeRF or 3D GS is, in practice, close to impossible.
Most methods therefore relax the problem by simplifying the lighting conditions considerably or restricting the calculation to no more than one reflection.
Even state-of-the-art methods such as Relightable 3D Gaussian are still far from fully separating specular and diffuse components, and shading is particularly difficult to handle.
The video I shared at the time showed the separated specular and diffuse components:
High-quality BRDF models are themselves valuable assets for engine developers and game studios. With the relatively simple BRDF formulations used in current learning-based approaches, faithfully recovering the effects of a complex environment light map remains a distant goal.
2. NeRF and Game Engines
Compared with relighting, which is closely tied to finding an optimal—or at least well-approximated—solution to the rendering equation, integration with game engines is in a somewhat better position.
First, I should clarify what the videos in the original article actually showed:
- The following video used a NeRF object in Blender.
- The background in the following Unity scene, which I put together as a game-like environment,
- was reconstructed from 360-degree camera footage using 3D Gaussian Splatting.
I am making this distinction because supporting NeRF and supporting 3D GS in a game engine involve very different levels of difficulty.
3D GS is close to a variation of a point cloud and renders scenes through rasterization, so integrating it into an existing game engine is relatively straightforward. The Unity plugin I referred to during the project and this Unreal Engine 3D GS plugin show that people working with game engines are actively supporting 3D GS, in contrast to NeRF.
An object represented by a NeRF, on the other hand, must be drawn pixel by pixel through ray casting, just as in the original NeRF formulation:
$$ C(r) = \int_{t_n}^{t_f} T(t) \cdot \sigma (\mathbf{r}(t)) \cdot c(\mathbf{r}(t), \mathbf{d}) \, dt \quad \text{where}\quad T(t) = \exp \left(-\int_{t_n}^{t} \sigma(\mathbf{r}(s)) \, ds\right) $$
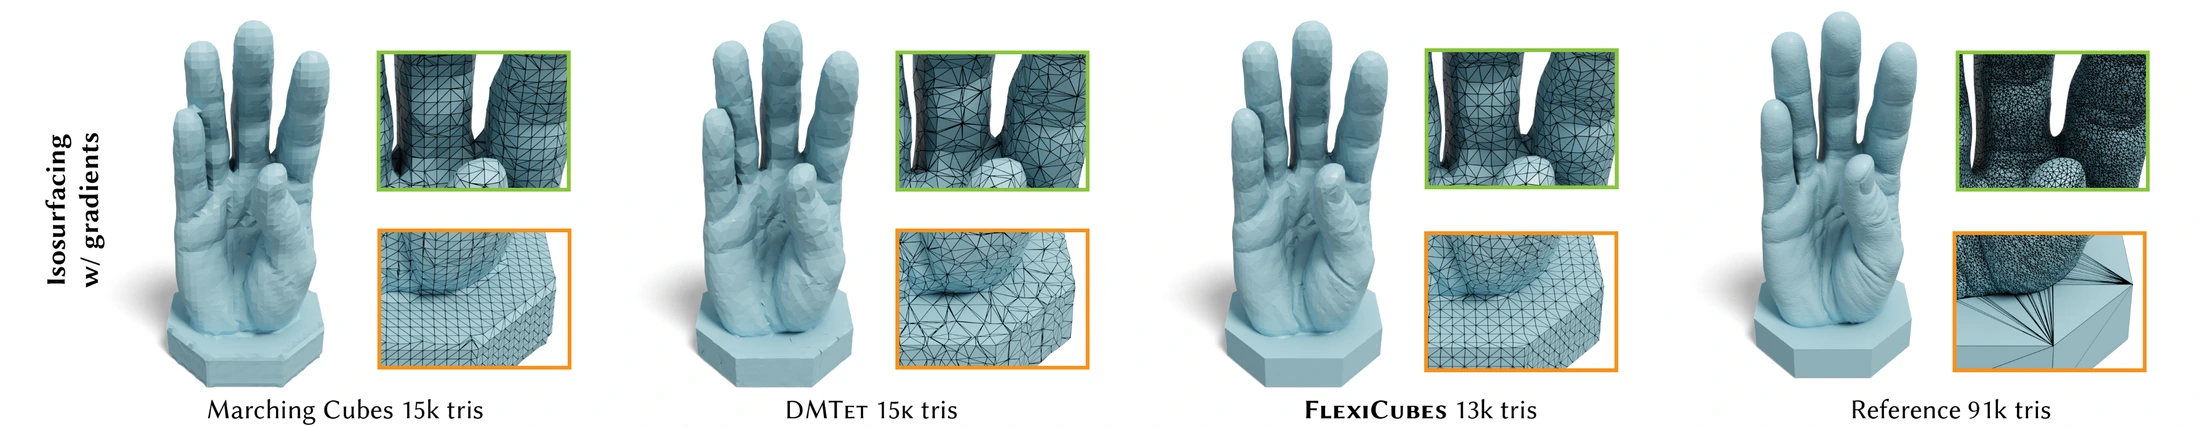
Rather than supporting this directly in a game engine—real-time rendering is already difficult enough that simply adding support would not make it practical for game production—the usual approach is to extract a polygonal mesh using Marching Cubes or DMTet, map textures onto it, and export it as an OBJ or FBX file.
The problem is that meshes converted from NeRF can have overly complex geometry, holes, cracks, and uneven textures compared with meshes created by artists. Meshing techniques tailored to neural rendering, such as FlexiCubes, are appearing, but the conversion quality is still short of what is needed to use NeRF objects directly in games.
At this point, a reasonable question might be:
Why not just use 3D GS instead of NeRF?
However, 3D GS has its own limitations. Splats can become visible when zooming in or out, and because the representation is not an MLP, areas that NeRF might represent smoothly can instead become excessively sharp. It cannot simply replace NeRF in every situation.
Converting 3D GS into a mesh is also harder than converting NeRF. Proposed approaches include treating the shortest scale axis as the surface normal, adding regularization, or learning an SDF alongside the Gaussian representation, but practical use still seems some way off.
Conclusion?
We are still in a transitional period. New techniques may appear ready to replace existing ones almost overnight, but their quality is still insufficient for production use.
Even in 2D generation, five or six years passed between GANs first producing high-quality human faces and generative models reaching a commercially useful level of quality—and that happened through diffusion, rather than GANs.
I suspect NeRF and 3D GS will need at least that much time. Or perhaps another technology will become dominant and reach the service stage, just as diffusion displaced GANs.